
インフォグラフィック・教育
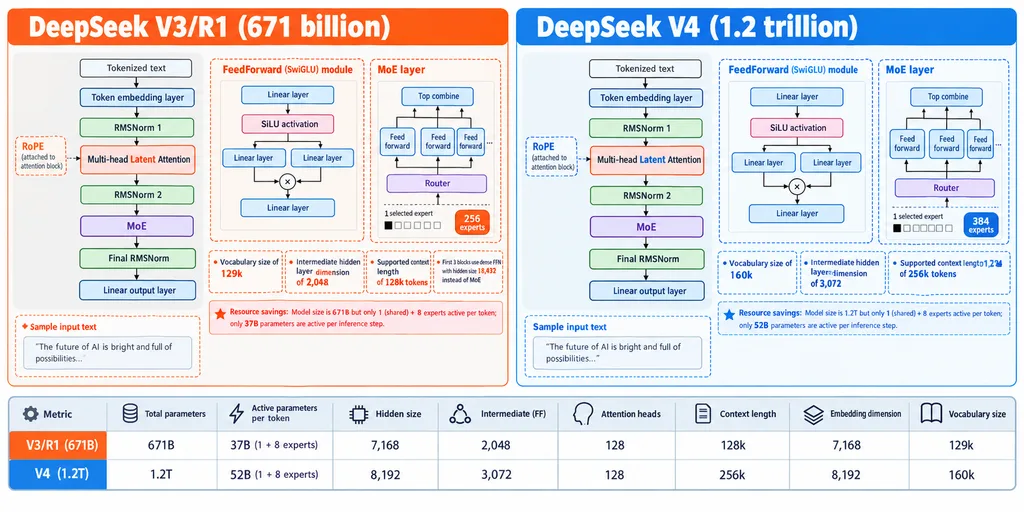
モデルアーキテクチャ左右比較インフォグラフィック
2つのトランスフォーマーモデルを並列比較するプレゼン用技術系統図を生成します。角括弧内のモデル名やパラメータ数を編集してカスタマイズ可能です。
インフォグラフィック技術図アーキテクチャ比較図スライド資料トランスフォーマー
プロンプト
{
  "type": "AIアーキテクチャの左右比較インフォグラフィック",
  "style": "クリーンな技術系統図、白背景、細い黒の輪郭線、角丸四角形、破線の引き出し線ボックス、色分けされたハイライト、プレゼンスライド風、ベクターインフォグラフィック",
  "canvas": {
    "aspect_ratio": "2:1",
    "resolution": "wide horizontal"
  },
  "title_row": {
    "left_title": "[DeepSeek V3/R1 (671 billion)]",
    "right_title": "[DeepSeek V4 (1.2 trillion)]",
    "left_title_color": "鮮やかなオレンジレッド",
    "right_title_color": "鮮やかなブルー"
  },
  "layout": {
    "columns": 2,
    "sections": [
      {
        "title": "[DeepSeek V3/R1 (671 billion)]",
        "position": "左半分",
        "count": 9,
        "labels": [
          "Vocabulary size of 129k",
          "FeedForward (SwiGLU) module",
          "Intermediate hidden layer dimension of 2,048",
          "MoE layer",
          "Supported context length of 128k tokens",
          "First 3 blocks use dense FFN with hidden size 18,432 instead of MoE",
          "Sample input text",
          "Embedding dimension of 7,168",
          "128 heads"
        ]
      },
      {
        "title": "[DeepSeek V4 (1.2 trillion)]",
        "position": "右半分",
        "count": 9,
        "labels": [
          "Vocabulary size of 160k",
          "FeedForward (SwiGLU) module",
          "Intermediate hidden layer dimension of 3,072",
          "MoE layer",
          "Supported context length of 256k tokens",
          "First 3 blocks use dense FFN with hidden size 24,576 instead of MoE",
          "Sample input text",
          "Embedding dimension of 8,192",
          "128 heads"
        ]
      },
      {
        "title": "下部比較表",
        "position": "下部全幅",
        "count": 10,
        "labels": [
          "Total parameters",
          "Active parameters per token",
          "Hidden size",
          "Intermediate (FF)",
          "Attention heads",
          "Context length",
          "Embedding dimension",
          "Vocabulary size"
        ]
      }
    ]
  },
  "left_panel": {
    "background": "ごく薄いグレーの角丸四角形",
    "main_stack": {
      "count": 8,
      "blocks": [
        "Tokenized text",
        "Token embedding layer",
        "RMSNorm 1",
        "Multi-head Latent Attention",
        "RMSNorm 2",
        "MoE",
        "Final RMSNorm",
        "Linear output layer"
      ]
    },
    "side_module": "左側のアテンションブロックに接続されたRoPE",
    "attention_block": {
      "label": "Multi-head Latent Attention",
      "accent": "Latentの文字にオレンジレッドのアクセント"
    },
    "feedforward_inset": {
      "title": "FeedForward (SwiGLU) module",
      "count": 4,
      "blocks": [
        "Linear layer",
        "SiLU activation",
        "Linear layer",
        "Linear layer"
      ],
      "diagram": "2系統の乗算後に射影"
    },
    "moe_inset": {
      "title": "MoE layer",
      "count": 5,
      "blocks": [
        "top combine node",
        "Feed forward",
        "Feed forward",
        "Router",
        "expert count badge 256"
      ],
      "details": "選択された1エキスパートを表す小さな黒い四角、エキスパートへの上向き矢印、点線の仕切り線"
    },
    "annotations": {
      "vocab": "Vocabulary size of 129k",
      "ff_dim": "Intermediate hidden layer dimension of 2,048",
      "context": "Supported context length of 128k tokens",
      "dense_first_blocks": "First 3 blocks use dense FFN with hidden size 18,432 instead of MoE",
      "resource_savings": "Resource savings: Model size is 671B but only 1 (shared) + 8 experts active per token; only 37B parameters are active per inference step"
    },
    "bottom_stats": {
      "count": 8,
      "items": [
        "Total parameters: 671B",
        "Active parameters per token: 37B (1 + 8 experts)",
        "Hidden size: 7,168",
        "Intermediate (FF): 2,048",
        "Attention heads: 128",
        "Context length: 128k",
        "Embedding dimension: 7,168",
        "Vocabulary size: 129k"
      ]
    }
  },
  "right_panel": {
    "background": "ごく薄いブルーの角丸四角形",
    "main_stack": {
      "count": 8,
      "blocks": [
        "Tokenized text",
        "Token embedding layer",
        "RMSNorm 1",
        "Multi-head Latent Attention",
        "RMSNorm 2",
        "MoE",
        "Final RMSNorm",
        "Linear output layer"
      ]
    },
    "side_module": "左側のアテンションブロックに接続されたRoPE",
    "attention_block": {
      "label": "Multi-head Latent Attention",
      "accent": "Latentの文字にブルーのアクセント"
    },
    "feedforward_inset": {
      "title": "FeedForward (SwiGLU) module",
      "count": 4,
      "blocks": [
        "Linear layer",
        "SiLU activation",
        "Linear layer",
        "Linear layer"
      ],
      "diagram": "左パネルと同様の構造"
    },
    "moe_inset": {
      "title": "MoE layer",
      "count": 5,
      "blocks": [
        "top combine node",
        "Feed forward",
        "Feed forward",
        "Router",
        "expert count badge 384"
      ],
      "details": "選択された1エキスパートを表す小さな黒い四角、エキスパートへの上向き矢印、点線の仕切り線、青枠による強調"
    },
    "annotations": {
      "vocab": "Vocabulary size of 160k",
      "ff_dim": "Intermediate hidden layer dimension of 3,072",
      "context": "Supported context length of 256k tokens",
      "dense_first_blocks": "First 3 blocks use dense FFN with hidden size 24,576 instead of MoE",
      "resource_savings": "Resource savings: Model size is 1.2T but only 1 (shared) + 8 experts active per token; only 52B parameters are active per inference step"
    },
    "bottom_stats": {
      "count": 8,
      "items": [
        "Total parameters: 1.2T",
        "Active parameters per token: 52B (1 + 8 experts)",
        "Hidden size: 8,192",
        "Intermediate (FF): 3,072",
        "Attention heads: 128",
        "Context length: 256k",
        "Embedding dimension: 8,192",
        "Vocabulary size: 160k"
      ]
    }
  },
  "global_notes": "左右対称レイアウトの高精細なTransformerアーキテクチャ比較図を作成。左右それぞれに大型スタック図1点とインセット図2点(FFNモジュールとMoE層)を配置。ブロック間を矢印で結び、微細な技術ラベルと引き出し線を配置。高密度なプレゼン風タイポグラフィ、左側はオレンジレッド、右側はブルーをアクセントカラーにし、下部に幅いっぱいの比較表を配置。"
}カスタマイズできる部分
生成する前に、プロンプトのこれらの部分を自分のテーマや文言に置き換えてください。
[DeepSeek V3/R1 (671 billion)]プレースホルダー[DeepSeek V4 (1.2 trillion)]プレースホルダー
プロンプトの詳細
- カテゴリ
- インフォグラフィック・教育
- モデル
- GPT IMAGE 2
- 1 枚あたりのコスト
- 1K:43 クレジット · 2K:86 クレジット · 4K:143 クレジット
- アスペクト比
- 2:1
- 追加日