
提示詞
{
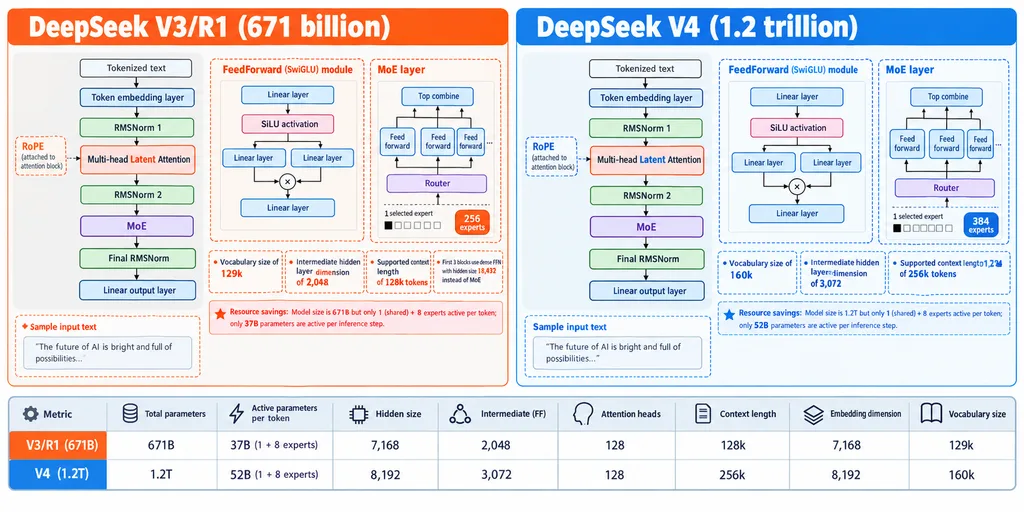
  "type": "並排式AI模型架構對比資訊圖",
  "style": "整潔的技術架構圖、白底、細黑色輪廓線、圓角矩形、虛線標註框、顏色高亮、簡報幻燈片美學、向量資訊圖",
  "canvas": {
    "aspect_ratio": "2:1",
    "resolution": "wide horizontal"
  },
  "title_row": {
    "left_title": "[DeepSeek V3/R1 (671 billion)]",
    "right_title": "[DeepSeek V4 (1.2 trillion)]",
    "left_title_color": "亮橙紅色",
    "right_title_color": "鮮藍色"
  },
  "layout": {
    "columns": 2,
    "sections": [
      {
        "title": "[DeepSeek V3/R1 (671 billion)]",
        "position": "左半部",
        "count": 9,
        "labels": [
          "Vocabulary size of 129k",
          "FeedForward (SwiGLU) module",
          "Intermediate hidden layer dimension of 2,048",
          "MoE layer",
          "Supported context length of 128k tokens",
          "First 3 blocks use dense FFN with hidden size 18,432 instead of MoE",
          "Sample input text",
          "Embedding dimension of 7,168",
          "128 heads"
        ]
      },
      {
        "title": "[DeepSeek V4 (1.2 trillion)]",
        "position": "右半部",
        "count": 9,
        "labels": [
          "Vocabulary size of 160k",
          "FeedForward (SwiGLU) module",
          "Intermediate hidden layer dimension of 3,072",
          "MoE layer",
          "Supported context length of 256k tokens",
          "First 3 blocks use dense FFN with hidden size 24,576 instead of MoE",
          "Sample input text",
          "Embedding dimension of 8,192",
          "128 heads"
        ]
      },
      {
        "title": "底部對比表格",
        "position": "底部全寬",
        "count": 10,
        "labels": [
          "Total parameters",
          "Active parameters per token",
          "Hidden size",
          "Intermediate (FF)",
          "Attention heads",
          "Context length",
          "Embedding dimension",
          "Vocabulary size"
        ]
      }
    ]
  },
  "left_panel": {
    "background": "極淺灰色圓角矩形",
    "main_stack": {
      "count": 8,
      "blocks": [
        "Tokenized text",
        "Token embedding layer",
        "RMSNorm 1",
        "Multi-head Latent Attention",
        "RMSNorm 2",
        "MoE",
        "Final RMSNorm",
        "Linear output layer"
      ]
    },
    "side_module": "左側注意力模組附帶RoPE",
    "attention_block": {
      "label": "Multi-head Latent Attention",
      "accent": "Latent字樣使用橙紅色"
    },
    "feedforward_inset": {
      "title": "FeedForward (SwiGLU) module",
      "count": 4,
      "blocks": [
        "Linear layer",
        "SiLU activation",
        "Linear layer",
        "Linear layer"
      ],
      "diagram": "雙分支相乘後投影"
    },
    "moe_inset": {
      "title": "MoE layer",
      "count": 5,
      "blocks": [
        "top combine node",
        "Feed forward",
        "Feed forward",
        "Router",
        "expert count badge 256"
      ],
      "details": "代表1個選中專家的黑色小方塊、指向專家層的向上箭頭、虛線分隔線"
    },
    "annotations": {
      "vocab": "Vocabulary size of 129k",
      "ff_dim": "Intermediate hidden layer dimension of 2,048",
      "context": "Supported context length of 128k tokens",
      "dense_first_blocks": "First 3 blocks use dense FFN with hidden size 18,432 instead of MoE",
      "resource_savings": "Resource savings: Model size is 671B but only 1 (shared) + 8 experts active per token; only 37B parameters are active per inference step"
    },
    "bottom_stats": {
      "count": 8,
      "items": [
        "Total parameters: 671B",
        "Active parameters per token: 37B (1 + 8 experts)",
        "Hidden size: 7,168",
        "Intermediate (FF): 2,048",
        "Attention heads: 128",
        "Context length: 128k",
        "Embedding dimension: 7,168",
        "Vocabulary size: 129k"
      ]
    }
  },
  "right_panel": {
    "background": "極淺藍色圓角矩形",
    "main_stack": {
      "count": 8,
      "blocks": [
        "Tokenized text",
        "Token embedding layer",
        "RMSNorm 1",
        "Multi-head Latent Attention",
        "RMSNorm 2",
        "MoE",
        "Final RMSNorm",
        "Linear output layer"
      ]
    },
    "side_module": "左側注意力模組附帶RoPE",
    "attention_block": {
      "label": "Multi-head Latent Attention",
      "accent": "Latent字樣使用藍色"
    },
    "feedforward_inset": {
      "title": "FeedForward (SwiGLU) module",
      "count": 4,
      "blocks": [
        "Linear layer",
        "SiLU activation",
        "Linear layer",
        "Linear layer"
      ],
      "diagram": "與左側結構相同"
    },
    "moe_inset": {
      "title": "MoE layer",
      "count": 5,
      "blocks": [
        "top combine node",
        "Feed forward",
        "Feed forward",
        "Router",
        "expert count badge 384"
      ],
      "details": "代表1個選中專家的黑色小方塊、指向專家層的向上箭頭、虛線分隔線、藍色邊框強調"
    },
    "annotations": {
      "vocab": "Vocabulary size of 160k",
      "ff_dim": "Intermediate hidden layer dimension of 3,072",
      "context": "Supported context length of 256k tokens",
      "dense_first_blocks": "First 3 blocks use dense FFN with hidden size 24,576 instead of MoE",
      "resource_savings": "Resource savings: Model size is 1.2T but only 1 (shared) + 8 experts active per token; only 52B parameters are active per inference step"
    },
    "bottom_stats": {
      "count": 8,
      "items": [
        "Total parameters: 1.2T",
        "Active parameters per token: 52B (1 + 8 experts)",
        "Hidden size: 8,192",
        "Intermediate (FF): 3,072",
        "Attention heads: 128",
        "Context length: 256k",
        "Embedding dimension: 8,192",
        "Vocabulary size: 160k"
      ]
    }
  },
  "global_notes": "生成高度對稱的超詳細Transformer模型架構對比圖。左右各包含一個完整模型堆疊以及2個內嵌結構圖(前饋模組與MoE專家層)。模組間附帶連線箭頭、細小技術文字與指引線。保持密集專業的幻燈片排版風格,左側使用橙紅色強調,右側使用藍色強調,底部附帶橫跨全寬的資料對比表。"
}可以替換的部分
生成前,把提示詞裡的這些部分換成你自己的主題或文案。
[DeepSeek V3/R1 (671 billion)]佔位符[DeepSeek V4 (1.2 trillion)]佔位符
提示詞資訊
- 分類
- 資訊圖與教育
- 模型
- GPT IMAGE 2
- 每張圖消耗
- 1K:43 點數 · 2K:86 點數 · 4K:143 點數
- 畫幅比例
- 2:1
- 收錄時間