
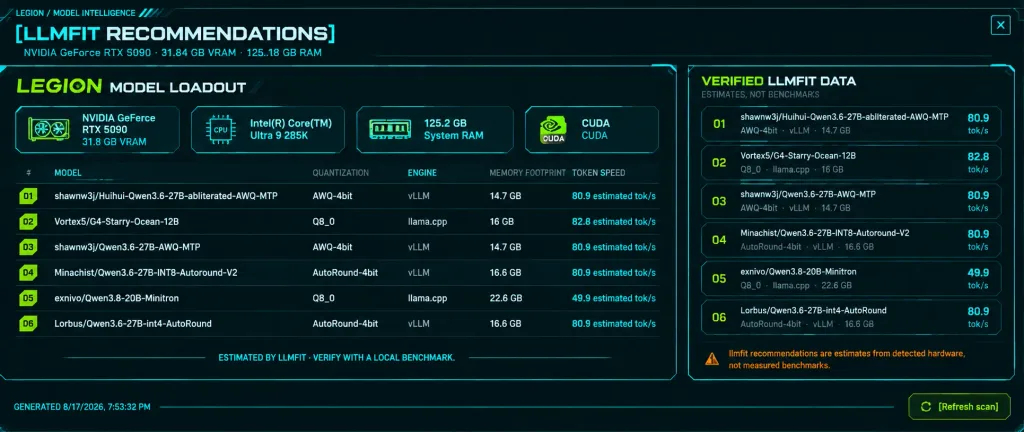
Futuristic AI Model Recommendation Dashboard
Generates an ultrawide cyberpunk desktop dashboard visualizing local AI model benchmarks and system specs. Customize the bracketed titles, button text, or GPU details to fit any workstation hardware.
Prompt
Dark futuristic dashboard infographic screenshot for [LLMFIT RECOMMENDATIONS], displaying local AI model performance metrics on an ultrawide desktop panel. Setting & Canvas: Ultra-wide 21:9 ratio computer monitor UI screenshot. Dark theme with pitch black and deep teal background, subtle ambient backlight glow, thin glowing neon cyan borders, fine scanline grid texture, and compact sci-fi terminal styling. Header: Top bar displays small label "LEGION / MODEL INTELLIGENCE", primary large title "[LLMFIT RECOMMENDATIONS]", subtitle "NVIDIA GeForce RTX 5090 · 31.84 GB VRAM · 125.18 GB RAM", and a square close-box icon on the top right. Left Panel (two-thirds width): Main card titled "LEGION MODEL LOADOUT" ("LEGION" in neon lime, remainder in white techno font). Exactly 4 horizontal hardware status tiles beneath: 1) NVIDIA GeForce RTX 5090, 31.8 GB VRAM with GPU icon; 2) Intel(R) Core(TM) Ultra 9 285K with CPU chip icon; 3) 125.2 GB system RAM with RAM module icon; 4) CUDA with circular CUDA emblem. Below hardware tiles, exactly 6 ranked rows with lime numbered badges (01-06), displaying model path, quantization, engine runtime, memory footprint, and token speed: 1) shawnw3j/Huihui-Qwen3.6-27B-abliterated-AWQ-MTP — AWQ-4bit — vLLM — 14.7 GB — 80.9 estimated tok/s 2) Vortex5/G4-Starry-Ocean-12B — Q8_0 — llama.cpp — 16 GB — 82.8 estimated tok/s 3) shawnw3j/Qwen3.6-27B-AWQ-MTP — AWQ-4bit — vLLM — 14.7 GB — 80.9 estimated tok/s 4) Minachist/Qwen3.6-27B-INT8-Autoround-V2 — AutoRound-4bit — vLLM — 16.6 GB — 80.9 estimated tok/s 5) exnivo/Qwen3.8-20B-Minitron — Q8_0 — llama.cpp — 22.6 GB — 49.9 estimated tok/s 6) Lorbus/Qwen3.6-27B-int4-AutoRound — AutoRound-4bit — vLLM — 16.6 GB — 80.9 estimated tok/s Bottom of left card features a centered neon divider with text: "ESTIMATED BY LLMFIT · VERIFY WITH A LOCAL BENCHMARK." Right Panel (one-third width): Titled "VERIFIED LLMFIT DATA" with subtitle "ESTIMATES, NOT BENCHMARKS". Lists exactly 6 compact verification cards numbered 01 to 06 in lime font, gray subtext, and cyan performance metrics: 80.9, 82.8, 80.9, 80.9, 49.9, 80.9 tok/s. Bottom warning note in orange: "llmfit recommendations are estimates from detected hardware, not measured benchmarks." Footer: Bottom left displays timestamp "GENERATED 8/17/2026, 7:53:32 PM". Bottom right features a lime-outlined clickable button labeled "[Refresh scan]" with a sync icon. Style & Constraints: Crisp, sharp digital HUD UI graphic, high-contrast condensed sans-serif technical typography, angular framing, no real-life humans or external photography, pure technical dashboard graphic.
What you can customize
Swap these parts of the prompt for your own subject or wording before you generate.
[LLMFIT RECOMMENDATIONS]placeholder[Refresh scan]placeholder“LEGION / MODEL INTELLIGENCE”quoted wording“NVIDIA GeForce RTX 5090 · 31.84 GB VRAM · 125.18 GB RAM”quoted wording“LEGION MODEL LOADOUT”quoted wording“LEGION”quoted wording“ESTIMATED BY LLMFIT · VERIFY WITH A LOCAL BENCHMARK.”quoted wording“VERIFIED LLMFIT DATA”quoted wording
Prompt details
- Category
- UI / UX Design
- Model
- GPT IMAGE 2
- Cost per image
- 1K: 43 credits · 2K: 86 credits · 4K: 143 credits
- Aspect ratio
- 21:9
- Added