
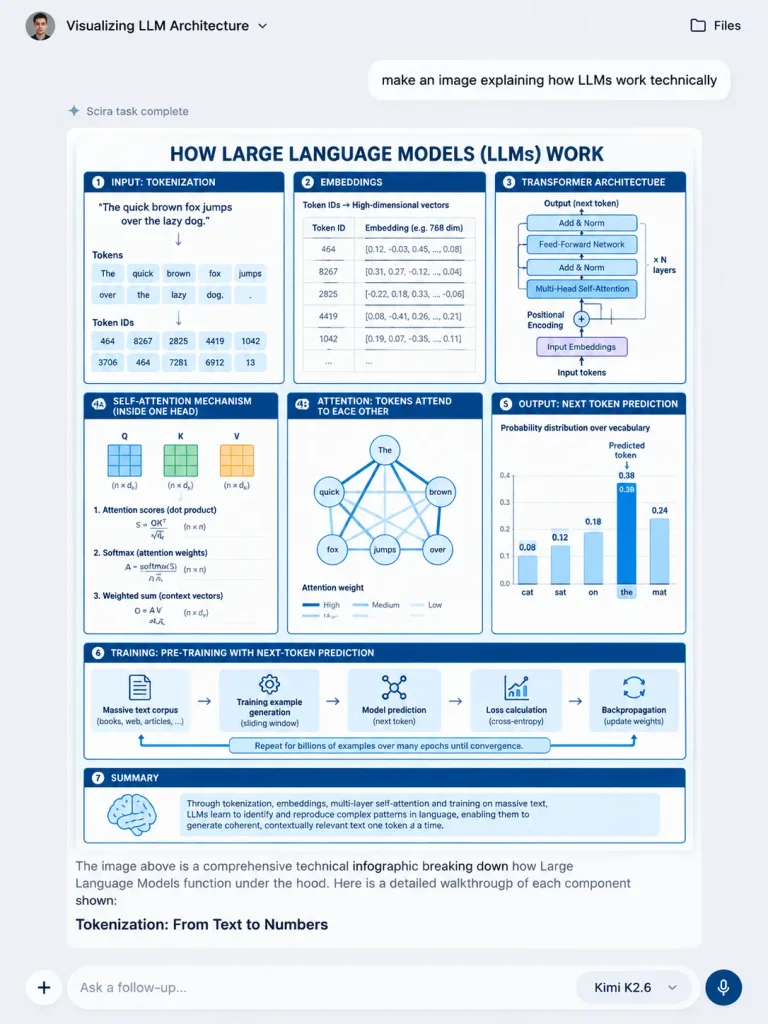
อินเทอร์เฟซแชท AI พร้อมอินโฟกราฟิกสถาปัตยกรรม LLM
สร้างภาพหน้าจอเว็บแอปแชท AI พร้อมอินโฟกราฟิกเชิงเทคนิคในตัว เปลี่ยนหัวข้อในวงเล็บเพื่ออธิบายแนวคิดทางเทคนิคอื่น ๆ
พรอมป์
A realistic vertical screenshot of a modern AI chat web application interface displaying an embedded technical infographic about [how Large Language Models (LLMs) work technically]. The app has a clean light gray background (#F4F4F6), subtle shadows, and crisp sans-serif typography. Chat UI layout: - Top bar: Circular user avatar on the left, conversation title "Visualizing LLM Architecture" with a tiny dropdown chevron, and a "Files" text button with a folder icon on the top right. - User message bubble: Rounded white pill/card near top center-right containing the text: "make an image explaining how LLMs work technically". - Status row: Directly below the prompt, reading "Scira task complete" with a tiny sparkle loader icon. - Assistant response card: Large central rounded card housing the generated infographic. - Assistant text: Below the infographic card, clean body text reading: "The image above is a comprehensive technical infographic breaking down how Large Language Models function under the hood. Here is a detailed walkthrough of each component shown:" followed by a bold section heading "Tokenization: From Text to Numbers". - Bottom dock: Rounded pill input bar with placeholder text "Ask a follow-up...", a plus (+) attach button on the left, model selector badge "Kimi K2.6" with dropdown chevron, and a circular microphone voice button on the right. Embedded Infographic Poster: A crisp blue-and-white engineering-style technical diagram titled in bold navy capitals: "[HOW LARGE LANGUAGE MODELS (LLMs) WORK]". Clean white background, navy borders, light-blue accents, organized into 8 panels: 1. "INPUT: TOKENIZATION": Sentence "The quick brown fox jumps over the lazy dog." split into token blocks with corresponding token IDs. 2. "EMBEDDINGS": Token IDs mapping to high-dimensional dense vector tables. 3. "TRANSFORMER ARCHITECTURE": Layered stack showing Add & Norm, Feed-Forward Network, Multi-Head Self-Attention, input embeddings, and positional encoding. 4A. "SELF-ATTENTION MECHANISM (INSIDE ONE HEAD)": Matrix representations for Q, K, V vectors, dot product attention scores, softmax, and weighted sum equations. 4B. "ATTENTION: TOKENS ATTEND TO EACH OTHER": Network graph of token nodes connected by attention-weight lines. 5. "OUTPUT: NEXT TOKEN PREDICTION": Bar chart of probability distribution over vocabulary tokens (cat, sat, on, the, mat), highlighting predicted token "the". 6. "TRAINING: PRE-TRAINING WITH NEXT-TOKEN PREDICTION": Horizontal 5-stage pipeline strip: massive text corpus, training example generation, model prediction, loss calculation, and backpropagation. 7. Process connecting arrow: "Repeat for billions of examples over many epochs until convergence." 8. Summary callout box: Brain icon with explanatory text on generalized pattern learning. Style: Vector schematic aesthetic, sharp lines, academic tech diagram, legible dense typography, no watermarks.
ส่วนที่ปรับแต่งได้
ก่อนสร้างภาพ ให้แทนที่ส่วนเหล่านี้ของพรอมป์ด้วยหัวข้อหรือข้อความของคุณเอง
[how Large Language Models (LLMs) work technically]ตัวแทนข้อความ[HOW LARGE LANGUAGE MODELS (LLMs) WORK]ตัวแทนข้อความ
รายละเอียดพรอมป์
- หมวดหมู่
- ออกแบบ UI / UX
- โมเดล
- GPT IMAGE 2
- ค่าใช้จ่ายต่อภาพ
- 1K: 43 เครดิต · 2K: 86 เครดิต · 4K: 143 เครดิต
- อัตราส่วนภาพ
- 3:4
- วันที่เพิ่ม